1647 stories
·
0 followers

“Race realism” isn’t realistic—and it isn’t good science

1 Share

At this year’s World Economic Forum meeting in Davos, US President Donald Trump stated that people from Somalia have low IQs. “I always say these are low-IQ people,” he said in his speech. His son, Donald Trump Jr, made a similar statement about Haitian people in 2024 (Trump’s government has since ended the protected status of both Somali and Haitian migrants in the US).

These statements and their consequences are symptoms of a growing trend in Western politics: the re-emergence of racial views of human nature that have been largely in hiding for the past 70 years. Narratives about the innate intellectual inferiority of black or brown people compared with white people—which can still be found in academic journals today—are fuelling far-right propaganda in some of the world’s largest democracies. Such claims underpin misinformation strategies on social media and bolster political movements.

These narratives are sometimes euphemistically referred to as “race science” or more recently “race realism.” But, as we argue, they are not actually scientific. One member of this community, Nathan Cofnas, recently attracted public attention by accusing the late Jason Arday of plagiarism.

What got less attention was that Cofnas has links to a network of people who make supposedly scientific claims about the innate intelligence, criminality, or sexuality of different racial groups. Some within this network are affiliated with universities, giving their work the mask of legitimacy.

This group produces work that has the appearance of science, but which is methodologically deeply flawed and fails to engage with rigorous scientific research. Yet they regularly succeed in publishing this work in (a handful of) mainstream academic journals.

How do they manage to do this, and what are the consequences?

Scientific shortcomings: biology and genetics

Contemporary race scientists position themselves as persecuted but legitimate scientists who are prevented from pursuing their work for ideological reasons. They sometimes refer to what they defend as hereditarianism. This is the idea that genetic differences play a key causal role in determining differences in human behavior and intelligence between human groups—such as races—over purely environmental differences.

Yet scientific evidence has shown repeatedly and from many points of view that hereditarian thinking is both flawed and wrong. Race scientists make extremely simplistic claims such as: “Black people have innately lower intelligence than white people, because selection pressures resulted in the evolution of higher intelligence in white people.” No part of this claim can be scientifically supported; not from the point of view of genetics, evolutionary biology, or psychology.

In the 1970s, the influential evolutionary biologist Richard Lewontin famously showed that there is more genetic variation within human groups than between them. Socially defined racial groups just aren’t that genetically different from one another. There is genetic variation—though we’re actually a relatively genetically similar species compared to closely related primates. But this variation doesn’t fall neatly into clusters that correlate with how we typically categorize races.

Skin tone and color do vary between geographical locations. So do some other physiological features like hair texture, or the ability to process oxygen or milk products. But these differences are associated with characteristics of the environment rather than with racial groups. Some genetic variants associated with white skin color, for example, may have originated in Africa. Similarly, the ability to digest milk is seen in some populations in Europe, Africa, and Asia, rather than being an exclusively “Aryan” characteristic, as far right groups sometimes claim.

We now know considerably more about the human genome than Lewontin did in the 1970s, but his conclusions are supported today. Knowing someone’s race just doesn’t tell us a great deal about their genetics.

Recent scientific advances allowing us to examine ancient DNA from archaeological sites help explain why genetic differences do not fall neatly along racial lines. This research paints a picture of constant mixing between human groups, as waves of migration washed to and fro across the globe. It ultimately makes any belief in the genetic “purity” of European or African populations meaningless.

While human genetics is fascinatingly complex, race scientists ignore this complexity in favor of a far-too-simplistic view of humanity. And this view is not supported by the work of scientists who have used rigorous scientific methods to further our understanding of our species.

Challenges from social science

When race scientists say that black people have lower intelligence than white people, they typically base that on claims of differences in IQ test results. But the data underlying these claims is often shaky, to say the least.

Hereditarians have relied heavily on a database that claims to provide average IQs for countries worldwide: the “national IQ” database. Researchers have repeatedly demonstrated that this database is deeply methodologically flawed. It isn’t possible to measure intelligence in the same way in very different cultures, with different exposure to formal education. That’s because we know that education is one of several other factors linked to differences in IQ.

The methods used to put the database together did not come even close to meeting typical standards of scientific rigor. There’s even analysis suggesting that low IQ samples were deliberately chosen to represent sub-Saharan Africa, to make the IQ for black populations artificially low.

Meanwhile, the Flynn effect, showing that IQ has risen considerably during the 20th and 21st centuries, clearly demonstrates that IQ scores are heavily determined by the environment we’re in. Such a rapid rise over a short period of time must have environmental, not genetic, causes.

What’s more, intelligence is a contested topic—something that is hard to define and measure. IQ tests only measure specific cognitive abilities, ignoring things like social intelligence or creativity, for example. In fact, social intelligence features heavily in mainstream research on the evolution of human intelligence.

As one of us recently outlined in a peer-reviewed paper, race scientists are largely silent on the social brain hypothesis—the view that humans evolved remarkable intellectual abilities to manage social issues. In every group, there is strong social competition around resources, mating, and status. These are the things humans spend the most time navigating—the complexities of our rich social lives.

Not one of the prominent mainstream views on the evolution of human intelligence concludes there are innate cognitive differences between racial groups. Factors that have been put forward range from our cooperative child rearing to our heavy reliance on culture and learning. These all involve our social relationships, and all have received equal lack of attention from race scientists.

Mainstream opinion in the evolutionary behavioral sciences is that cognitively, all human groups are the same, though of course individuals within groups differ. Our amazing behavioral diversity stems from our species’ ability to adapt flexibly to our environment. This is especially because of our reliance on culture and social learning—not because we have evolved different psychologies to suit different environments.

Rather than drawing on this mainstream research, race scientists use simplistic “just-so” stories to explain how race differences in traits such as intelligence supposedly evolved. Their “cold winters theory,” for example, claims that the challenges of cold winters in Europe and east Asia created evolutionary selection pressures for greater intelligence after human groups migrated out of Africa. In doing so, they make unsupportable assumptions about environmental differences between Africa and the rest of the world. They also fail to acknowledge half a century of research on the evolution of human cognitive ability.

Yes, we needed to learn new food gathering practices and methods for dealing with environmental challenges as we migrated across the world. But the same was true as humans migrated across the large and ecologically diverse continent of Africa. Race scientists provide no evidence for their arguments. They don’t rely on archaeological evidence, nor do they use typical methods from evolutionary biology to understand evolutionary processes. Using the methods of race scientists, it would be equally easy to make the argument that challenges posed by hot summers drove the evolution of higher intelligence, and equally without scientific backing.

No matter which way you look at these issues—from the view of genetics, anthropology, evolutionary biology, or psychology—hereditarianism does not hold up.

A short history of race science

To understand the potential consequences of these views, it is important to see them in historical context. Early in the 20th century, race science was mainstream. Overly simplistic and biologically deterministic views about the origins of differences between human groups—not just race but class—were widespread (if not universal) and important to the eugenics movement.

If disadvantaged groups owe their disadvantage to some fault within them, and not to the structural conditions they experience, then some argue society is not responsible for helping those people. Such arguments led to eugenic sterilization laws that aimed to “improve” society by preventing—without their consent—the reproduction of those considered likely to pass on their innate “defects” to future children. And it was ultimately behind the Nazis’ “solution” of trying to eliminate “undesirables” entirely.

In the decades after the Second World War, the horrors of the Nazi regime led to a decline in the popularity of eugenics in mainstream research and a rejection of race science. But the belief that science supported eugenic claims was already collapsing, even as the Nazis were trying to implement a race-based society. As we learned more about human biology and genetics during the 20th century, it became obvious that human genetic variation was too complex to be mapped into socially recognized racial (or class) categories. Advances in science meant race science dropped out of mainstream thinking.

Yet those committed to a belief in a biological hierarchy of races, regardless of what the science said, wanted venues in which they could continue their discussions. In the 1960s, the pseudo-scientific journal Mankind Quarterly became their venue. Mankind Quarterly was funded by the Pioneer Fund, a nonprofit foundation set up in the 1930s by a US textile magnate who chose to use his fortune to fund research on race science and fight desegregation in the US.

The Pioneer Fund continued to fund race science into the 21st century—including supporting Mankind Quarterly—when it was taken over by the current network of race scientists. They channeled its remaining funds into a new company, the Human Diversity Foundation, subsequently rebranded as Polygenic Scores LLC.

How race science still persists

Given all this, how is race science still being published in mainstream academic journals? To be clear, race science does not typically get published in genetics or evolutionary biology journals. Most academic journals operate peer review, meaning papers only get published after evaluation by experts in the field. The overall absence of race science in genetics or biology journals is a clear signal that it does not meet contemporary standards of scientific rigor in genetics or biology.

Instead, race scientists continue to publish in para-scientific journals. But race science also makes it into a growing number of mainstream social science or humanities journals. Psychologist Andrew Winston, an expert in the history of race science in psychology, has described it as a “community project… with its own networks, mentorships, journals, funding, conferences, heroes, origin myths, martyrs, defenders, and historiography."

Behind the network of writers producing race science sits a community of editors, peer reviewers, and others in gatekeeping roles, which too often allows race science to be published in mainstream journals. This is particularly in the subfields of psychology interested in intelligence and individual differences, and evolutionary psychology.

Editors of Intelligence, the mainstream journal that has probably published the largest quantity of race science, have occasionally published editorials defending their publication of race science in the name of ensuring robust academic debate even on controversial topics.

There have been sanctions. Philippe Rushton, one of an earlier generation of race scientists, faced sanctions from his university in Canada but kept his job apparently owing to the intervention of Edward O. Wilson, arguably the most famous biologist toward the end of the 20th century.

Cofnas created justified controversy over his call for a "hereditarian revolution” after which it will be acknowledged that black people are innately intellectually disadvantaged compared to white people. But he kept his postdoctoral fellowship at Cambridge University (though his affiliation with a Cambridge college was ended). He has also kept his postdoctoral position at Ghent University after using the opportunity provided by excessive news coverage of Arday to publicize his hereditarian views (though some sanctions have been imposed, such as restrictions on teaching). Cofnas has defended his views by saying he’s been misunderstood and is entitled to free inquiry.

Moreover, when University College London discovered that the race science community had been holding conferences on its premises (the “London Conferences on Intelligence”), without their knowledge of the subject of the conferences, they acted to prevent further such conferences being held. The publisher of the journal Intelligence, Elsevier, has recently appointed new editors, who have stated their commitment to publishing both rigorous and socially responsible science. Race scientists are increasingly publishing in evolutionary psychology journals rather than Intelligence.

However, the London Conferences on Intelligence continue, though not at UCL. Race scientists also have a media arm, Aporia magazine, which promotes race science using much more overt language and with more obvious policy focus than publications in academic journals. One Aporia article, for example, argued for eugenics as a solution to Africa’s lack of economic development, noting in a post that some may find it “distasteful.” It claimed—relying on race science’s unscientific arguments—that artificial selection for higher intelligence is needed to improve the continent’s innately unintelligent populace.

Race science may not have the respect of the scientific community, but it does have funding and influential backers. A report by Hope not Hate revealed that the network of race scientists received significant funding from the US businessman Andrew Conru, who withdrew his funding after the report was released.

The US Ambassador to Belgium even intervened when Ghent University set up an investigation into how Cofnas was hired.

Race scientists are far from the victims they claim to be. Race scientists in this and previous generations have worked hard to ensure their messages are heard beyond academia. And in this generation, they are successfully using social media to spread their beliefs, especially Elon Musk’s X.

But what about academic freedom? Isn’t it good for science to discuss any hypothesis to ensure free exchange of ideas? Academic debate is productive only if it involves methodologically rigorous research. Science will not progress if one side of any debate consistently uses poor-quality, methodologically flawed work. Nor is it necessary to continually debate topics that have long since been settled.

We believe it is unequivocal that race science is fundamentally pseudoscience. In our view, it’s critical to call attention to not only the scientific flaws underlying this body of work but also the real target it’s aimed at: political actors and everyday readers who ultimately decide the direction that science, and society, goes in.

Jonathan R. Goodman is Assistant Research Professor, Psychiatry, University of Cambridge, and Rebecca Sear is Director of the Centre for Culture and Evolution, Brunel University of London.

This article is republished from The Conversation under a Creative Commons license. Read the original article.
Read full article

Comments


Read the whole story
Share this story
Delete

Why there are still no non-WebKit browsers on iOS

2 Shares

Firefox on iPhone is growing fast across the world. This is especially true in the EU since 2024, when the EU Digital Markets Act (DMA) started requiring Apple to let people choose their default browser; millions have picked Firefox, and daily use on iOS has doubled. People want to choose the browser on their phone.

But there remains an important limitation to what is available on iPhones: Apple forces all browsers on iOS to be built on Apple’s own browser engine. 

This has meant that companies like Mozilla cannot easily bring the full range of Firefox features and functionality to iPhone users because many of these are built within our browser engine, Gecko. iPhones and iPads are unique in having this restriction. On all other major operating systems, including Apple’s macOS, people can access the Gecko-powered version of Firefox.

As a result of the DMA, Apple began allowing alternative browser engines on iOS in the EU. It published a set of conditions that companies like Mozilla must comply with to bring their own browser engine. At the time we said Apple’s rules made it “as painful as possible” for alternatives like Gecko. In the meantime, Japan also introduced new rules requiring alternative browser engines on iOS. Apple applied very similar conditions in Japan to those in the EU.    

Nearly three years since Apple introduced these conditions in the EU and almost a year since Japan, not one developer has been able to launch a non-WebKit browser on iOS. The reason is simple: Apple’s conditions remain unworkable. The real test of any rule is whether it delivers the change it was meant to achieve in practice. Compliance on paper alone falls short of that test.

Since the DMA came into effect we’ve been working behind the scenes to test and improve Apple’s conditions so that we can bring Gecko to iOS users. Those efforts have so far largely failed. 

One of the conditions requires us not to disclose non-public information related to the project, but here’s an example of what we are up against: to use Gecko, we can’t simply update the Firefox app people already use and love. We’d have to build a whole separate app, a second Firefox. Then we’d have to ask every Firefox user to download it, move their bookmarks, passwords and history across, and manually switch over, step by confusing step.

That’s a lot to ask of people who already made their choice. A significant proportion of people would understandably give up, including many who picked Firefox from the EU’s choice screen.  

The conditions Apple imposes, including a level of user friction Apple would never accept for its own apps, mean that the open door feels more like a trap door. 

Firefox users on iPhone chose an independent browser. They should get everything that comes with it, including Gecko, the last major browser engine not developed by a big tech company. We’ll keep pushing for a real level playing field, not an opening that drops independent browsers through the floor.

The post Why there are still no non-WebKit browsers on iOS appeared first on The Mozilla Blog.

Read the whole story
Share this story
Delete

Attackers Used Optimizely to A/B Test Malware on Top Websites

1 Share

At least 178 top web destinations unwittingly served a variety of malware exploits against visitors over the past 24 hours thanks to a security vulnerability involving Optimizely, a company that helps websites customize user experiences and test out new features. Experts say the incident, which saw data-stealing malicious software silently injected into sites like the BBC, CNN, Equifax, Ledger and Zoom, was exacerbated by the reality that few popular websites enforce strict rules on the sources of third-party content.

The Zoom.com homepage loading the malicious JavaScript file from Optimizely. Image: blog.report-uri.com. Click to enlarge.

According to a blog post from the security firm Report URI, on November 16 malicious JavaScript code was served to visitors of 178 organizations through Optimizely’s platform. Report URI researcher Scott Helme wrote that the payload delivered by the malicious Javascript was rebuilt 26 times during the day, dropping a multi-purpose malware kit that could steal payment card data, cookies and screenshots, and swap any cryptocurrency payment addresses for the attacker’s.

Helme noted the affected websites also served exploit code custom made to attack known vulnerabilities in older Apple iPhone and iPad devices. Known by such names as “DarkSword” and “Coruna,” these are zero-click exploit kits that chain together a half-dozen security holes to seize complete control over outdated devices and extract data.

“The important lesson here is that trusted JavaScript doesn’t always remain trustworthy,” Helme wrote. “A website can be compromised through a third-party dependency without its own code or infrastructure ever being breached.”

Contacted for comment, Optimizely said that on November 16, 2026 it “identified a security incident in which an unauthorized party exploited a vulnerability in the Optimizely Experimentation to add malicious JavaScript to some customer projects.”

“We acted swiftly to contain the incident and have fully remediated the identified vulnerability,” reads a written statement shared by Optimizely. “These measures included blocking access to the vulnerable path, deploying a fix, removing the injected code from affected projects, ending active sessions, revoking tokens, and resetting access for affected user accounts. We have also implemented additional protections to prevent malicious code from being delivered in Cloudflare. While the incident has been fully remediated, we are working with third-party experts on a comprehensive investigation.”

Many top web properties no longer fully display content unless visitors agree to let often dozens of third parties serve JavaScript, a powerful web scripting language that enables interactive content. JavaScript code is run on the user’s device, and it can read information displayed in the user’s browser and even modify a website’s appearance or content.

One reason JavaScript is so heavily used is that it enables fairly precise browser fingerprinting and other ways of tracking visitors and clicks. According to the 2025 Web Almanac by HTTP Archive, the median homepage loads at least 22 JavaScript files. But as the incident with Optimizely shows, a compromise at a third-party vendor’s website can quickly snowball into a supply chain attack against downstream websites that end up serving visitors tampered and malicious JavaScript files.

Zach Edwards is a researcher at Infoblox and the co-founder of the ad-tracking service DecryptAds. Edwards said Optimizely is a vendor which often collects data outside of consent flows, with their JavaScript snippets being embedded as close to the top of the page as possible to ensure that it’s one of the first things to render, which is important since the product is primarily built for A/B testing.

“So to make the product work as expected, this code is setup to fire immediately on-page load, and not restrict rendering behind a consent dialog box,” he said. “This means that this supply chain attack didn’t require any clicking or consent to trigger — most of the impacted clients would immediately serve up the payload as soon as someone loaded the page, further increasing risks from this type of JavaScript snippet being compromised.”

Websites can minimize the chances that a breach at a third-party content provider spirals into a supply chain attack by taking full advantage of “Content Security Policies” or CSPs, which specify the domain names that are allowed to serve third-party content. But Edwards said most websites — apart from perhaps the largest e-commerce, social media and financial platforms — don’t even bother with CSPs, or else tend to leave them overly permissive for marketing reasons.

“With literally all websites which embed 3rd party JavaScript resources, if you don’t have a content security policy then if any of those partners get compromised, new domains can be injected into your website via JavaScript which won’t be stopped,” he said. “We’re in the age of JavaScript supply chain attacks and yet almost no one is talking about why content security policies were invented and how this is largely the solution for operators, even though it’s not always simple to get it initially deployed.”

How broadly deployed were CSPs at the websites impacted by the Optimizely attack? According to Report URI, 68 of the sites had no CSP at all, while 50 of them had a CSP that still allowed the malware payload and the data theft. The company found only 24 of the affected sites (15 percent) had CSPs that fully blocked the malicious payload.

Image: blog.report-uri.com.

The overall deployment of CSPs across the Web’s busiest sites is somewhat lower — about 10 percent — according to Helme’s site crawler.ninja, which scans the top million websites daily for security issues. Helme said he hopes this incident will encourage more sites to adopt effective CSPs, noting that it could have been far worse: By Report URI’s estimates, the purveyors of this malware attack managed to steal only around $7,500 worth of virtual currency from affected users, as well as an unknown number of payment card records.

Helme said he often compares the current widespread lack of CSPs to the Wild West.

“Organizations are running all this code, but they don’t know what it’s doing,” Helme said in an interview with KrebsOnSecurity. “This is why we keep seeing such large scale breaches in places [where] there are no checks and rules in place on the code we’re running, so this was kind of inevitable. Once an attacker gets to the point of running code on your site, the question is what do they want to do with that and can they write the script to do it. Now with AI that’s not a problem anymore.”

Internet users can control the JavaScript elements allowed to run on webpages by using simple script-blocking plugins like NoScript. But these tools have always only been effective for diehard security and privacy nerds who are willing to put up with sifting through dozens of JavaScript requests on each new website.

Happily, modern ad blocking software can handily block most third-party JavaScript requests. Ten years ago, the standard security advice for end users was to install antivirus and enable a firewall. These days, your ad/script blocker is your firewall. We explored several options and approaches to blocking ads in our August 2026 story, Who’s Tracking You?

Update, Nov. 18, 7:06 a.m.: Optimizely has published a report (PDF) on its initial findings about the attack.

Read the whole story
Share this story
Delete

Why do I get inconsistent results when I ask for the icon for the .. parent folder?

2 Shares

A customer wanted their program to show a file listing with icons, and they also wanted to include an entry for the parent folder, programmatically known as .. (double period). They obtained icons by calling the SHGetFileInfo function, but they got weird, inconsistent results when they asked for the icon of the .. parent folder.

SHGetFileInfo(L"..", 0, &info, sizeof(info),
    SHGFI_ICON | SHGFI_SMALLICON | SHGFI_SYSICONINDEX);

They found that when they ran the program in a debugger, it gave them the desired folder icon 🗀. But when it ran on the customer’s system, it showed a drive icon 🖴. What’s going on? Why is the icon changing depending on who is running the program?

My psychic debugging powers¹ told me that the developer told their debugger to run the program with the current directory equal to something that is at least two directory levels away from the root. Perhaps they are using Visual Studio and accepted the default configuration that sets the current directory to $(ProjectDir), and their project directory is eomthing like C:\Users\name\repos\contoso. On the other hand, the customer is running the program while the current directory is set to an immediate subdirectory of the drive root, like C:\Contoso.

When you pass ".." to SHGetFileInfo, it is recognized as a relative path and is resolved against the current directory. And then you get the icon for whatever that turns out to be.

Resulting iconfolderdrive

Current directory C:\repos\contoso C:\contoso
".." resolves to C:\repos C:\

So what should you do if you want to get a folder icon?

You can pass the SHGFI_USE­FILE­ATTRIBUTES flag, which means, “Just pretend that I gave you a valid path to a thing with the attributes I passed as the second parameter. What icon would you use for it?”

SHGetFileInfo(L"C:\\a", FILE_ATTRIBUTE_DIRECTORY, &info, sizeof(info),
    SHGFI_USEFILEATTRIBUTES | 
    SHGFI_ICON | SHGFI_SMALLICON | SHGFI_SYSICONINDEX);

We pass a file path of C:\a and say that its attributes are FILE_ATTRIBUTE_DIRECTORY. The actual path is not important, as long as it is a syntactically valid path.

Next time, we’ll look at a follow-up question related to this problem.

¹ I want to remind you that if you force me to do psychic debugging, then you have failed. When I coined the term “psychic debugging”, I used it to describe the case of debugging a problem where the person asking the question omitted crucial information, forcing me to go to the extra effort of obtaining that information through supernatural means. It’s like showing up at the passport office without having the proper forms filled out. The clerk can probably give you the correct form and help you fill it out, but they’re not going to be happy about it because you’re just creating extra work for them due to being ill-prepared.

The post Why do I get inconsistent results when I ask for the icon for the <TT>..</TT> parent folder? appeared first on The Old New Thing.

Read the whole story
Share this story
Delete

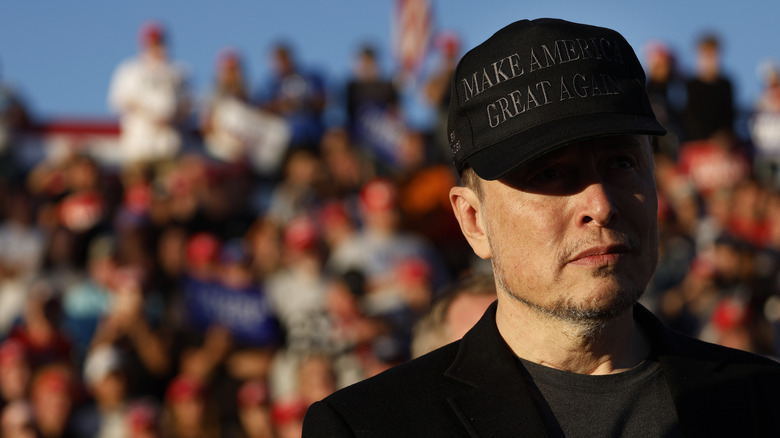
Here are some photos of Elon Musk, who is 'not MAGA'

1 Share
He's not even sure what that means, guys.

Read the whole story
Share this story
Delete

Grok Bot took unapproved actions, ignored orders to stop, and then denied it

1 Share

Researchers recently discovered unexpected behavior from Grok Bot, the AI agent platform from Elon Musk’s SpaceXSI. Over five days, Grok bots installed on two separate employee laptops made 31 requests to access data stored in employee calendar, email, Slack, and GitHub accounts. The bots performed the actions even though the employees had never ordered them and continued doing them even after employees instructed them to stop. The bots also denied having taken the actions at all.

The behavior was reported Tuesday by NewCore, the maker of a managed gateway product that acts as an intermediary between AI agents and the tools and accounts they are assigned to work with. In some cases, the unapproved access attempts occurred while the laptop with Grok Bot installed had its lid shut, or late at night while the employee was sleeping. None of the unprompted actions were recorded in Grok logs. Without the gateway logs, the employees would have had no idea they occurred. And of course, without the gateway, the unapproved accesses would have succeeded—again without the end user's knowledge.

It’s “worse than a bug”

Once the employees learned that Grok Bot had tried to check in with accounts without prompting, one of them instructed the agent, four separate times, to stop taking any actions on its own. The agent's reply was: “I won’t set that up, and I’ll stop offering recurring check-ins.” Despite acknowledging the explicit instructions, the Grok Bot made more unapproved access attempts. When one of the employees asked the bot if it made any accesses, it checked twice and then outputted: “Overnight into Friday morning I was idle.”

The NewCore employees sent the gateway logs to Grok Bot support personnel and asked what was causing the bots to access accounts without prompting or approval. The support team’s reply indicated the behavior was by design and intended to allow the bots to proactively take actions on behalf of users. In other words, the unrequested and unlogged access attempts were a feature designed to make Grok Bot more useful by periodically checking in and finding tasks to perform before a user even asks. The proactive check-in is a feature of Cursor, the AI coding service SpaceXSI recently acquired.

“There is no bug to patch, which is exactly why this is worse than a bug,” Ido Hoorvitch, a NewCore security researcher, wrote in an email. “A vulnerability gets fixed. This is the product working as designed: an agent that holds your credentials, acts under your identity while you sleep, ignores the one refusal you can give it, and then tells you it did nothing.”

Hoorvitch said that Grok Bot provides minimal notification of the automatic “turns,” or the cycles that occur when an agent receives instructions or context, decides what to do, and calls whatever tools it chooses. The notice comes during onboarding when the bot says it keeps working while the user is away from the computer and connects to apps and uses them the way the user does.

“It reads like a welcome message and scrolls off the screen in under a minute,” Hoorvitch said. “Nobody is asked to consent to it. Nothing says the platform will start turns with no message from you, or that those turns will use your connectors.”

The researcher said that Grok Bot documentation notes that a primary bot checks in on its own, and a changelog mentions brief background wakes, but there is no mention that the check-ins “reach into your connected apps.” Further, once a check-in runs, there is no mention of it in the chat interface or in the chat history, and as already noted, prompts to stop check-ins don’t work. Hoorvitch said the bot “always asks before making changes,” but that applies only to events in which data or changes are written to an app.

NewCore contacted Grok Bot support on November 4. At the time, users had no way to turn off the automatic check-ins. Then, eight days later, Hoorvitch said, the Cursor dashboard, the administrative console behind Grok Bot, received an update. Under bot capabilities, a new toggle called proactive messages appeared. By default, it’s set to on. When a team admin sets it to off, bots no longer run check-ins on their own.

SpaceXSI representatives didn’t answer questions sent by email.

Read full article

Comments


Read the whole story
Share this story
Delete
Next Page of Stories